48 GB
Nano Ultra 48
Memory-rich AI laptop, 14 to 16 inch
Request a priceHYPERCUBE and HYPERQ, developed by Quantum AI Connect and brought to India by World One. Thirteen current range entries, from personal AI to campus infrastructure, plus two next-generation designs: SuperPod Ultra and Titan 13.

India's demand for AI computing is growing faster than conventional data centres can be planned, financed and built. A modular data centre turns the building into a product: engineered once, integrated in a factory, accepted before it ships and added in steps.
Every module passes through the same four gates, whether it is a single rack or one of the nine modules in a Factory 9 block.
Seven HYPERQ systems for people and teams. Six current HYPERCUBE range entries for enterprises and governments, plus two next-generation designs: the SuperPod Ultra and Titan 13. Explore each system, its specifications and an illustrative exterior rendering.
Memory-rich AI laptop, 14 to 16 inch
Request a price
Balanced professional laptop
Request a price
Sovereign build
Request a price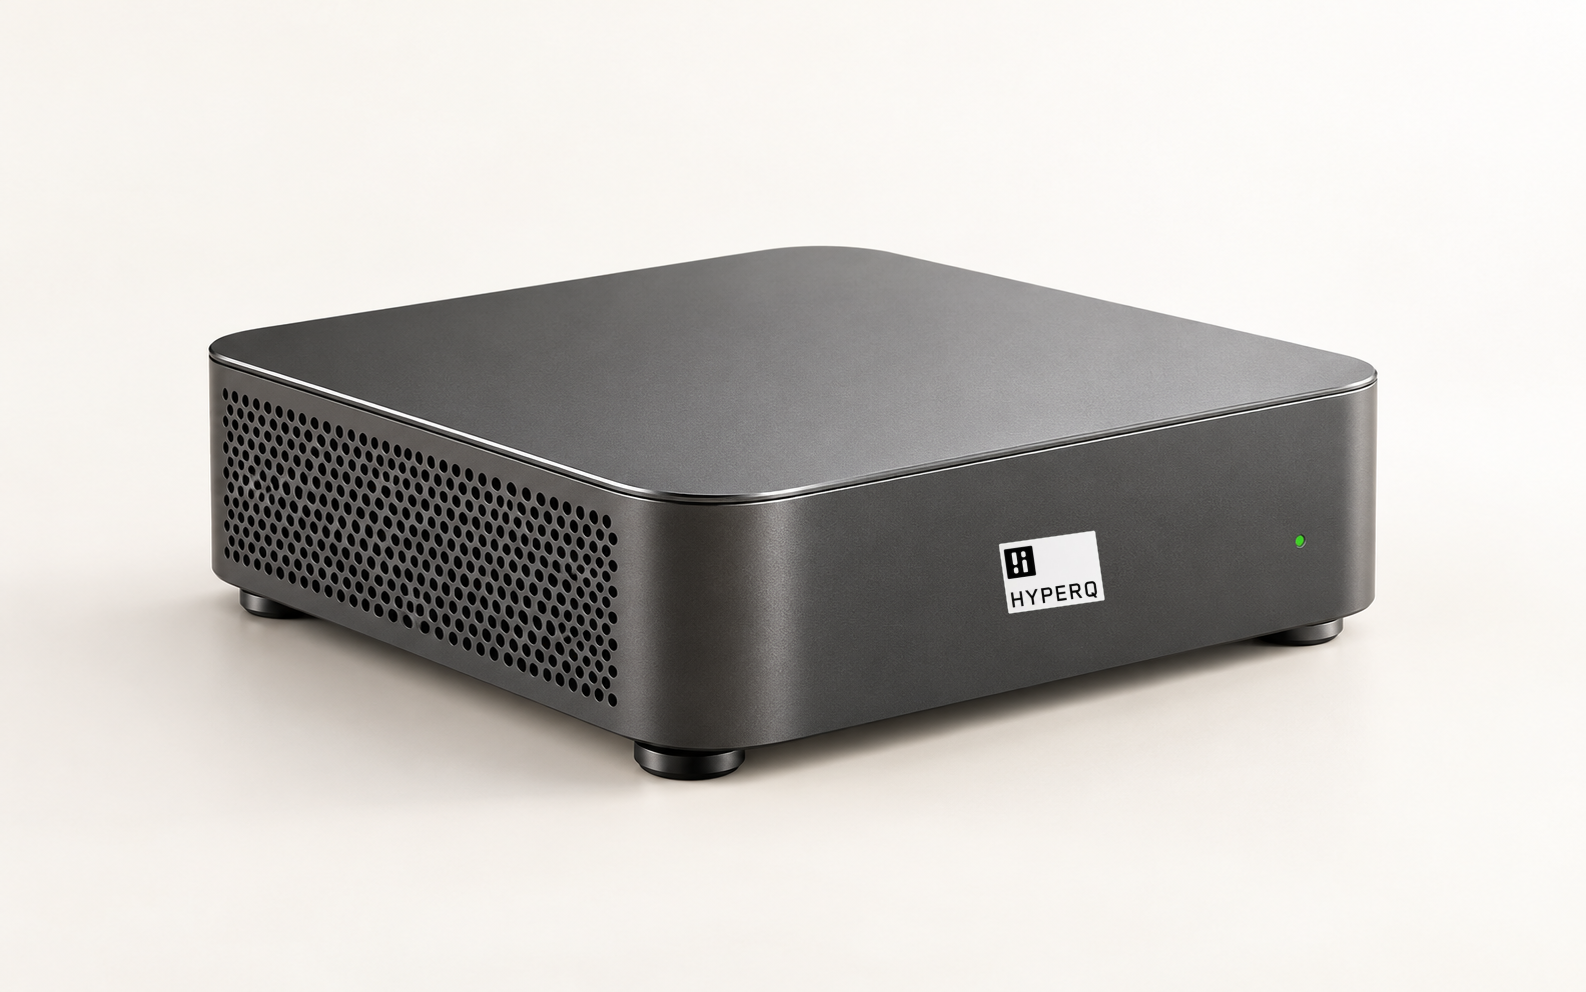
One GB10 node
Request a price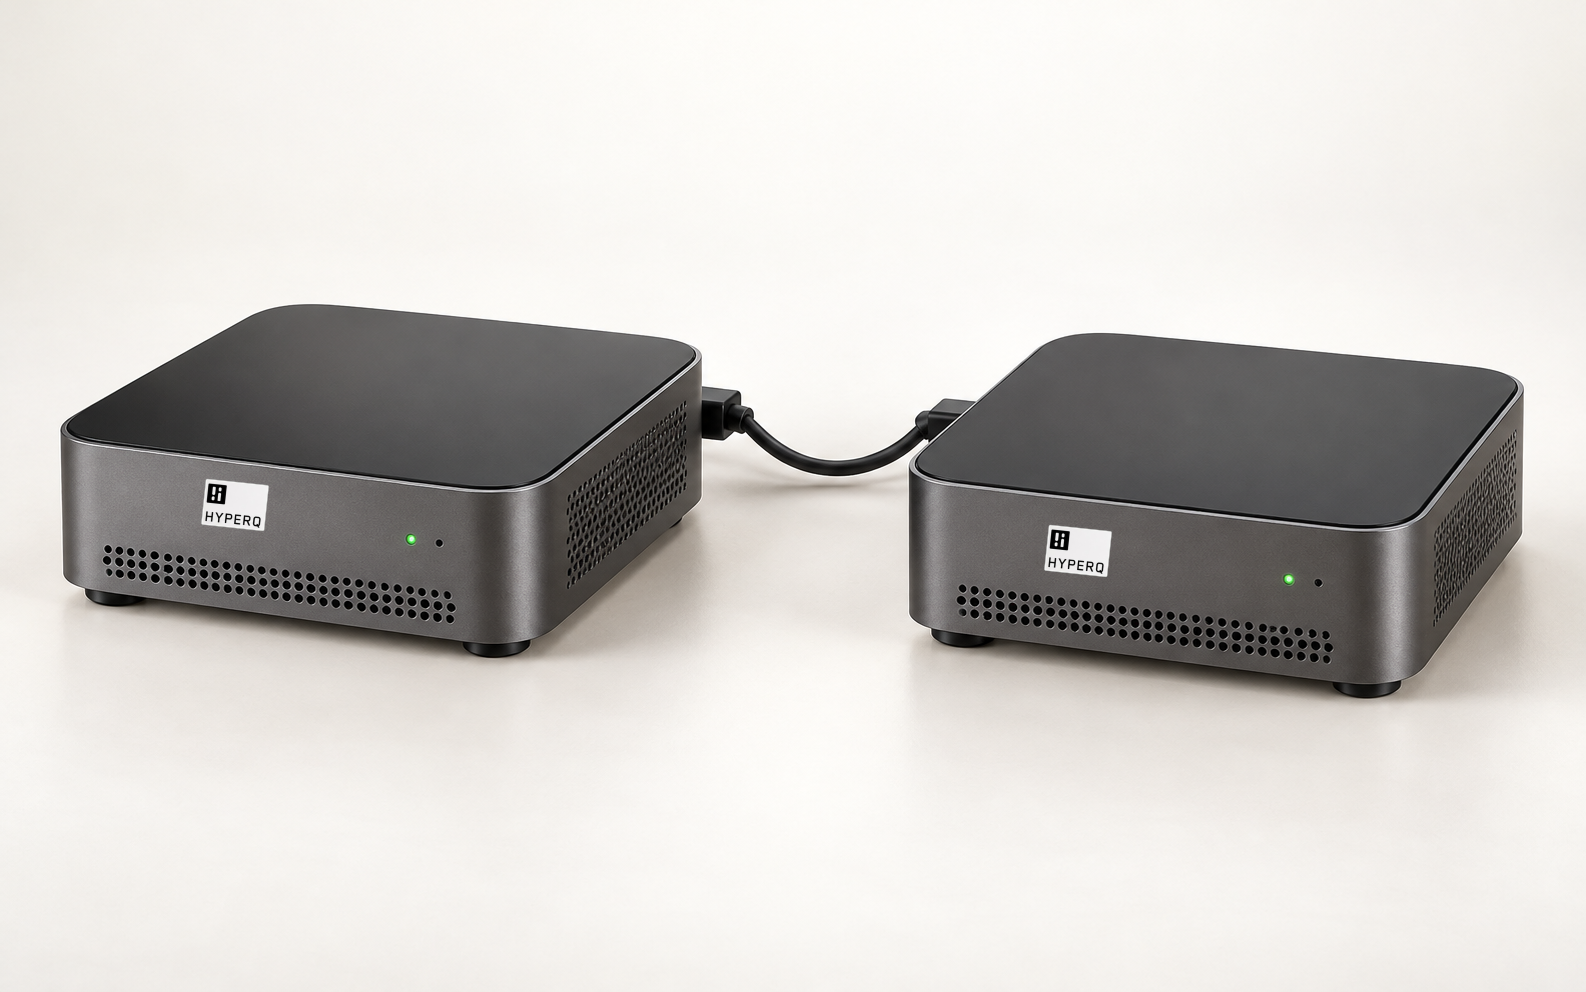
An officially linked pair
Request a price
Eight independently scheduled nodes
Request a price
Deskside frontier station
Request a price
Managed enterprise rack
Request a price
Modular regional inference cell
Request a price
Four-node private AI cloud
Request a price
Rack-scale AI module
Request a price
High-assurance rack-scale module
Request a price
Nine-module AI factory
Request a price
Next-generation Vera Rubin reference architecture. Sixteen racks and nine packages, by design.
Explore the architecture
SuperPod Ultra, next generation
Request a priceReference figures for each system. Final configuration, pricing and delivery are confirmed by quotation for a named country and end user.
| System | Compute | Memory | Power | Status | Price |
|---|---|---|---|---|---|
| Rack R8Managed enterprise rack | 8 x RTX PRO 6000; 32,000 AI TOPS | 768 GB GDDR7, aggregate | 6 to 12 kW | Components shipping | Request a price |
| Edge Cell E32Modular regional inference cell | 32 x RTX PRO 6000; 128,000 AI TOPS | 3.07 TB GDDR7, aggregate | 25 to 40 kW IT | Budgetary architecture | Request a price |
| Core Cell C32Four-node private AI cloud | 32 x B300; 576 PFLOPS FP4 sparse. Vera Rubin edition: 1.6 EFLOPS NVFP4 | About 8.4 TB HBM3e | 60 to 90 kW IT | Budgetary architecture | Request a price |
| Prime Cell P72Rack-scale AI module | GB300 NVL72; 1.44 EFLOPS FP4 sparse. Vera Rubin edition: 3.6 EFLOPS NVFP4 | 37 TB, one NVLink domain | 135 kW rack TDP | Subject to allocation | Request a price |
| Sovereign Cell S72High-assurance rack-scale module | GB300 NVL72, high assurance. Vera Rubin edition: 3.6 EFLOPS NVFP4 | 37 TB; 1 to 2 PB encrypted storage | As Prime Cell P72 | Accreditation required | Request a price |
| Factory 9 G576Nine-module AI factory | 8 x GB300 NVL72; 11.52 EFLOPS FP4 sparse. Vera Rubin edition: 28.8 EFLOPS NVFP4 | 296 TB fast memory | 1.25 to 1.45 MW IT | Reference architecture | Request a price |
| SuperPod UltraNine packages · design target | 16 Vera Rubin NVL72 racks; 1,152 Rubin GPUs (target) | Subject to final qualified rack configuration | 5.98 MW IT design envelope | Reference architecture; not yet built | Discuss the architecture |
| Titan 13 G864SuperPod Ultra, next generation | 12 x Vera Rubin NVL72 per block; 864 Rubin GPUs; 43.2 EFLOPS NVFP4 inference | About 896 TB fast memory per block | About 2.6 to 3.2 MW IT per block, planning | Next generation; planning architecture | Discuss the design |
One frozen reference configuration per block, built in the factory and accepted three times before it carries a customer's workload.
Workload, sovereignty requirements and site conditions fix one frozen reference configuration for each block.
Each module is integrated and tested in the factory, and its acceptance evidence travels with it.
By road and by sea, one module per trailer, with power, cooling and network connections ready to mate.
Set on its plinth, connected and commissioned, then accepted on site and under the customer's workload.
NVIDIA Blackwell Ultra servers and racks for your own facility, or built into HYPERCUBE modules. Supply is by quotation and subject to allocation and export authorisation.
World One works in partnership with Quantum AI Connect, the Abu Dhabi company that owns and develops HYPERCUBE and HYPERQ.